Webcam still
Local vision
Crop stays on this booth
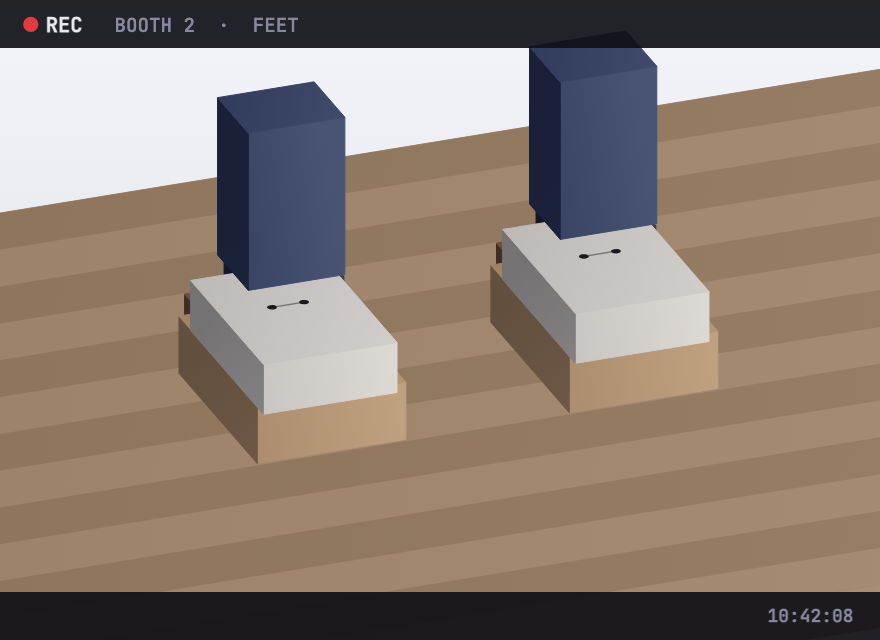
Profile Feet
White leather trainer, gum sole, cropped at the ankle.
Product search receives this sentence, not the frame.
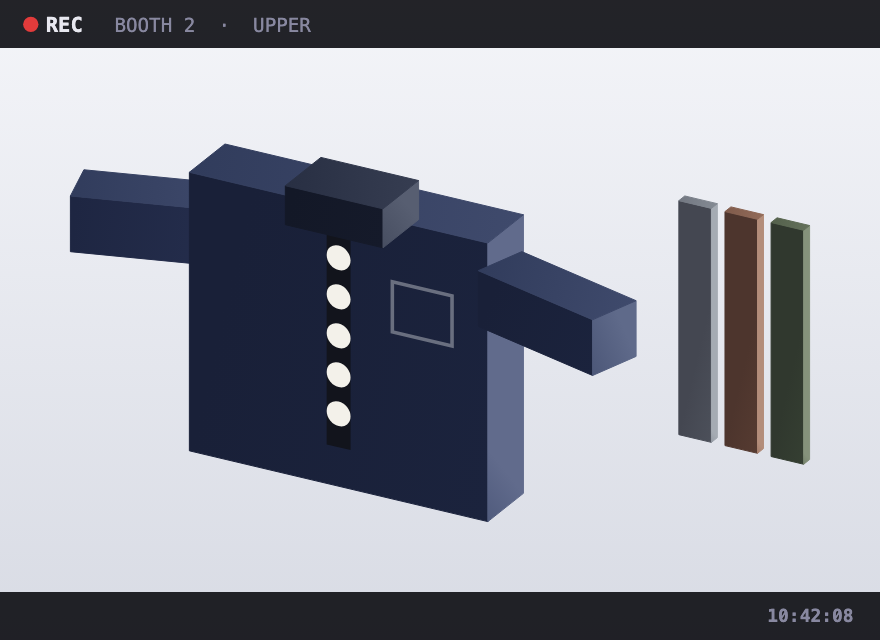
Profile Upper
A navy overshirt, no footwear visible.
The sentence stops at the torso. No shoe is invented.
10:41 · Feet
White leather trainer, gum sole, cropped at the ankle.
10:44 · Torso
A navy overshirt, no footwear visible.
Search uses the sentence for the crop in front of the camera. The other read stays on the session until the shopper leaves.
Preferred model is down
A missing tag falls back to a plain default: adult, a neutral presentation, casual, and the full region. Garments outside the frame are not invented.
| Order | Model | Result |
|---|---|---|
| 1 | Preferred vision model | not loaded |
| 2 | Lighter local model | standing by |
Parsed block on the session
<response>
<age_band>30 to 40</age_band>
<presentation>feminine</presentation>
<region>feet</region>
<style>court, gum sole</style>
<sentence>White leather trainer, gum sole, cropped at the ankle.</sentence>
</response>